AI tester over 11 weeks: 77 bugs from the agent, 16 from the human
A Claude Code session diary: 277 agent hours, 94 confirmed finds, where a reference pays off, and why an agent hour does not replace a human hour.
Developer news without the noise — My Dev News in Telegram.
Tag
All blog posts with this tag.
A Claude Code session diary: 277 agent hours, 94 confirmed finds, where a reference pays off, and why an agent hour does not replace a human hour.
LLM quality checks: public task sets, arenas, model judges, safety, product regression, and online signals — what each test measures and what it cannot see.
A feature is an investment that does not end at release. How to account for build, verification, support, and failure cost — and why you should test in proportion to blast radius, not coverage percentage.
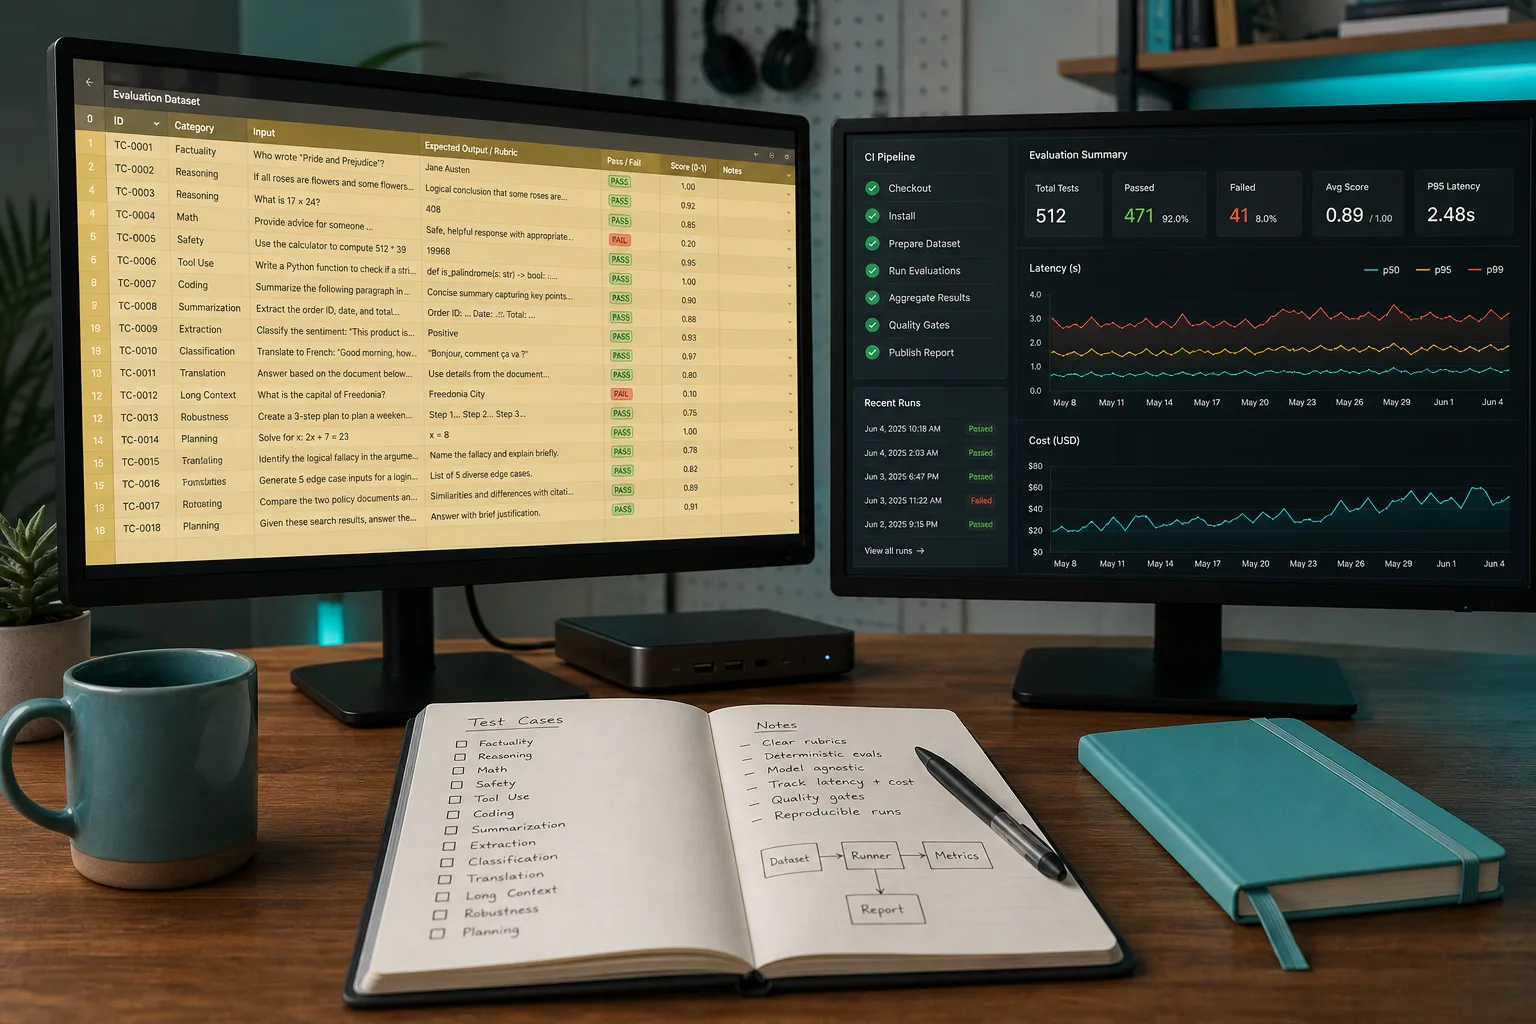
Build an AI evaluation harness that connects golden datasets, retrieval and generation metrics, CI regression gates, shadow traffic, release controls, observability, and LLM gateway FinOps.
Habr case study: from Vanessa Automation to native TestClient in Python — where Codex stalled for a week, Fable 5 mapped the protocol in a day for qa-mcp.