

Contents
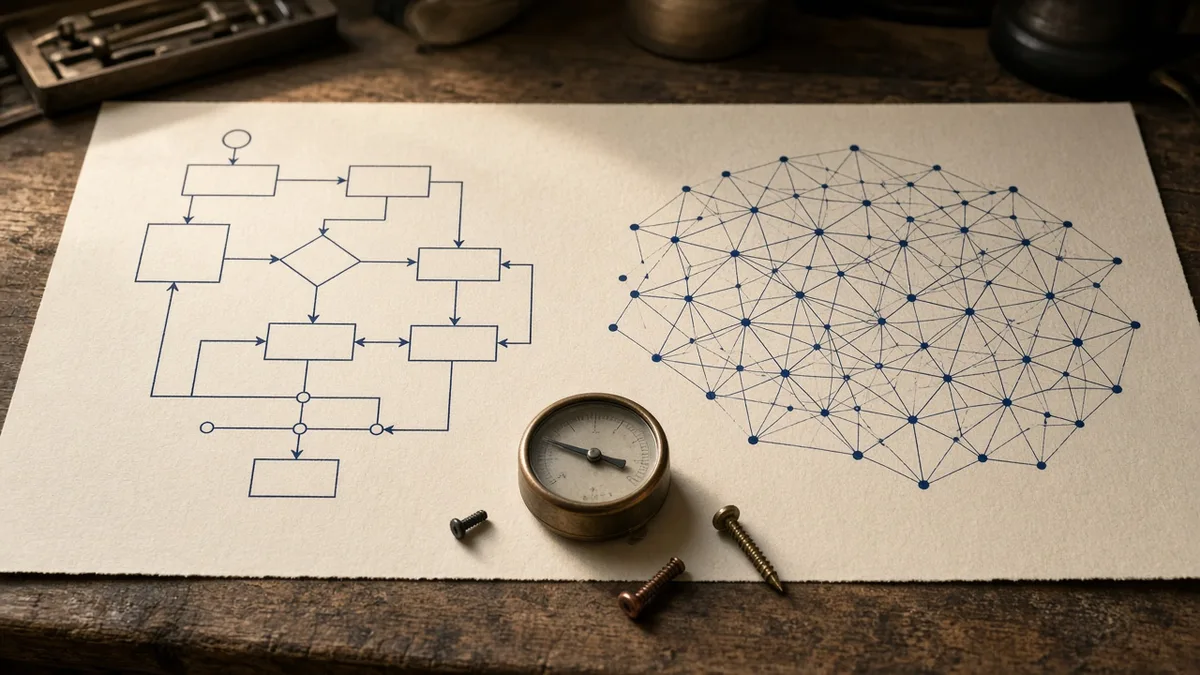
A sheet hangs on the workshop wall. It says how to test whether a number is prime: divide by candidates up to the square root. Anyone who can read the sheet gets the same answer on the same number. Next to it is a workbench. On the bench sit a frame, a stack of pages with handwritten digits, and a gauge. Screws adjust the frame. The gauge shows how far the current setting misses the label on the page. You turn the screws until the needle drops.
Two jobs get paired more often than they should. Write a function that says whether a number is prime. Build a system that recognizes a handwritten digit, even though nobody listed every way to draw a seven. Both produce a computational system. What differs is how the behavior gets there.
In the first case the behavior is written as steps. In the second you specify a frame of possible computations, examples, an error criterion, and a procedure that fits numeric parameters. Training does not cancel programming, and it does not produce a separate mind. It changes the object of the work. Beside the program text sits a process that forms parameters, and with them the system's abilities.
The sheet and the bench mean the same thing below. The sheet holds an explicit algorithm. The bench holds the architecture, the data, and the criterion used to fit parameters. The position of the screws holds the saved state of a trained model.
Key takeaways
A trained model stays a computational system inside a program. Its behavior comes from architecture, data, an error criterion, and fitted parameters. The source text often does not change.
The line "programs follow rules, models learn" is too coarse. A program can contain a trainable piece. A model runs as software. Compare two ways of assembling behavior. They do not become mutually exclusive kinds of objects.
Generalization is checked on new examples. Accuracy on a held-out set says how the system behaved on that data. It is not a proof of correctness for every future case.
Weights are not an encyclopedia and do not replace a citable document. Parameters take part in turning input into output. A specific fact is unreliable to pull back out. Where you need a standard's version and a clause number, document search and ordinary code checks sit beside the model.
The developer does not leave. They choose the task and the line past which the result must not ship. Data, architecture, and the metric belong to the same job. When a task has a known mathematical solution, an explicit algorithm is usually more honest, cheaper, and calmer than a model.
A prime goes on the sheet; a handwritten digit is fitted at the bench
A prime is an integer greater than one that is divisible only by one and itself. That definition already contains an algorithm. For a modest n, test divisors from two up to the square root of n.
def is_prime(n: int) -> bool:
    if n < 2:
        return False
    d = 2
    while d * d <= n:
        if n % d == 0:
            return False
        d += 1
    return True
With the same input and the same environment the function behaves predictably. The failures are ordinary program failures: a wrong condition, integer overflow, a forgotten n < 2. You hunt them with tests on known primes and composites. On a chosen range the test can be exhaustive, because the rule is complete.
A handwritten digit is built differently. A seven may have a crossbar or not, may be thick or thin, slanted, or stained by the pen. Contour, curve, and proportion breed exceptions fast. A rule such as "a vertical stroke plus a top shelf means a one or a seven" breaks on the next handwriting. The sheet on the wall grows, and each new writer brings a case the sheet does not contain.
At the bench the work is different. Take an image and the correct label. The model, with its current parameters, emits a guess. Measure how far the guess misses the label. Shift the parameters so the miss on this batch of examples shrinks. Then check images that were not in training. The classic teaching set of handwritten digits is built that way: a picture and a digit answer. It does not list every legal stroke.
One step is easier to see on a particular seven. The picture enters the network. Ten numbers come out, one per digit. Suppose the seven gets little mass and the one gets a lot: the model is reading the stick and ignoring the crossbar. The loss, often cross-entropy, assigns a large penalty because the correct label received a small share. The backward pass shows which parameters pulled the answer toward a one. The optimization step nudges those. The next similar seven has a better chance of a larger share. This is still optimization of a penalty on examples. The sentence "how people draw a seven" is not written into the file as its own line.
Generalization is the property that matters here, and it is easy to overrate. New examples can differ from the training ones. A good result on a held-out set means the system hits the label more often on those pages. It does not prove that the next seven, written on damp paper by someone else, will be read. Google's introductory machine learning course separates error on the data used to fit parameters from error on data that never entered that fit. The second is a practical check of generalization. It does not become a certificate of universal correctness.
The person does not drop out of this work. They choose the task and the architecture. Examples, the metric, and the reading of errors stay with them. The job moves off a sheet that lists every case and onto the design of a process that has to digest those cases.
Same code, different behavior
In the narrow sense, a program is text where the logic is stated explicitly. Instructions, conditions, state, error handling. The developer decides what the system does on each input they provided for. With fixed data and a fixed environment the result often repeats. Programs have exceptions too: a heuristic, randomness, configuration that changes without a new build, code that rewrites its own state. Predictability often comes with an explicit algorithm. It is not a law of nature.
A model, in the sense used here, is a trained computational structure. It has four working parts, and they should not be glued into one word.
Architecture sets which operations the system can perform at all. How many layers, which connections, what input size, what shape of answer. An empty frame on the bench does not yet recognize digits. It only limits what kind of computation can happen inside it.
Parameters, usually called weights, are a numeric state. They affect how input becomes output. The same frame with the screws in different positions gives different answers. A weight file stores that state. The file by itself executes nothing. Without the architecture code, the input format, and the inference procedure, it is a bag of numbers.
Data and the loss function answer what the system is being fitted to, and by which criterion. For a digit the criterion usually penalizes a wrong label. Another task gets another criterion. The optimization algorithm says how to move the parameters so the penalty on training examples shrinks. For layered networks the gradient with respect to the parameters is computed by a backward pass. The name of the procedure matters more than the metaphor. This is optimization of a chosen criterion. Knowledge does not appear as its own line because of it.
A running application is a separate thing. The model occupies one node in it. Around that node sit a request queue, input checks, logs, and a fallback if the model is silent or answers outside an allowed range. Confusing the weight file with that application is like taking the drawing of the frame for the machine already standing on the shop floor.
That is why "programs follow rules, models learn" falls apart at the first hybrid. A trainable block sits in the code. The model is called from an ordinary function. Beside it are a database, a set of rules, and a tool the model may ask to run. The map of how language models are adapted shows the same ladder: pretraining changes parameters, document search inserts a source for the duration of an answer, and a call to an external interface lives in the program around the model. What is worth comparing are ways of assembling behavior. In an industrial system the objects almost always share one stack.
Training turns the screws; it does not rewrite the sheet
After training the source text is often the same. What changes is the parametric state. The same architecture, on the same input, starts answering differently because the numbers in the transform are different. That state can be saved, loaded, and run again. A repeat run with the same file and the same code should give the same answer on the same input, if the inference procedure has no randomness. If the answer drifts, look for a mismatch in the code version and the weights. Then look at preprocessing and the hardware. The model's mood is irrelevant.
Three cards keep the levels from mixing. The first card is architecture: a description of the frame and of the computation rules, usually code. The second is weights: a snapshot of the settings after training. The third is a running instance: that snapshot executes on a particular machine, with a particular input format and a particular inference procedure. The PyTorch documentation draws the same line between defining a module, its parameters, and calling the module on data. Until the third card exists, the word "model" does not yet mean a system that accepts requests.
The same architecture with different weights yields different abilities. One setting reads digits. Another, in the same frame but after different data and a different criterion, may do a neighboring task or none at all. The release consequence is practical. A behavior version is the architecture code, the parameter file, and the input preparation together. A commit number is not enough.
Input preparation breaks the pair more quietly than people expect. During training the picture was resized, a mean was subtracted, and the channels were laid out in one order. At call time someone forgot the subtraction or swapped the channels. The architecture is the same, the weight file is the same, and the answers are already someone else's. Looking for a "corrupted model" there is wasted time. Check the chain up to the first number that enters the network. The same thing happens with text for a language model: a different split into pieces, or a different special marker at the start of the request, changes the input even though the parameter file was not touched.
The sheet on the wall is still there. The training code, the loop over examples, saving the file, and loading it before a request remain a program. Training does not replace the sheet. It adds a protocol by which the bench fits the screws.
The engineer's loop moves from editing text to editing the process
The classic loop on the sheet is short and familiar. Gather requirements. Design the algorithm. Implement it. Check known cases. Fix the text if a case disagrees with the rule. For a prime this loop is honest: you change a condition, and the behavior changes exactly where you wrote it.
The loop at the bench is longer, and the fix rarely starts at the line that "failed." First state the task and the metric. Then prepare the data and hold out a slice on which parameters must not be fitted. Choose an architecture and a loss. Compute the prediction, the error, and the parameter update. Look at the held-out slice. At the end, check an independent set that took no part in decisions during training. If the gauge needle fell on the training pages and rose on new ones, that is overfitting: the setting memorized the training pages instead of a pattern that transfers.
The engineer sets constraints, a quality criterion, and the fitting mechanism. The algorithm searches for parameters inside that frame. The setting it finds may contain regularities the person never wrote down one by one. That does not mean the result appeared without a design. The frame, the sample, the penalty, and the stopping rule remain human decisions. A lucky setting does not cancel those decisions. It carries them out.
Say plainly what is gained and what is lost. You gain tasks where a manual list of rules falls apart. Handwriting and a noisy picture. Speech, and a draft wording drawn from a body of text. You lose a direct view of every internal step, and the old confidence that a wrong answer can be pointed at in a single condition. Other duties show up instead. Data has to be collected and checked. Errors have to be read as a distribution, not as one counterexample. Behavior has to be repeatable: the same data, the same code, the same order, if the result must repeat. After release you have to notice that the input has moved relative to the training sample. That is drift. The world in the requests changed, and the screws stayed on the old setting.
The metric you trust at the bench is its own job, not a tail on training. How to choose measures for classification, vision, text recognition, and language models is covered in the piece on neural network quality metrics. Without that fork, the bench loop optimizes the wrong needle.
You also have to be able to repeat the setting, or the words "the same model" and the thing on the shop floor diverge. Keep a snapshot of the data and the training code. Keep the parameter file and a description of how input was prepared for the network. If any one of those moves, the gauge on new pages is already about a different system. A prime needs no such kit. The function text and a test on a range are enough. For a handwritten digit, the kit is the product.
A comparison you should not treat as a wall
The table describes typical cases. Do not treat it as a law. A heuristic program, a probabilistic algorithm, rules with a trainable piece, and a network inside a rigid pipeline sit between the columns. Read the rows as a hint about where to look first.
| Criterion | Explicit algorithm | Trained model |
|---|---|---|
| Where behavior comes from | Mostly from text and rules | From architecture, data, the training procedure, and parameters |
| How behavior is changed | Edit code, configuration, or input | Change parameters, architecture, context, or the surrounding software |
| New cases | Follows the written algorithm | Uses learned regularities when they transfer |
| How it is checked | Tests and, where possible, a proof of a limited property | Statistical evaluation and scenario tests |
| Typical failure | An implementation bug, a wrong condition, a wrong premise | Bad data, a skewed sample, weak generalization, a wrong answer |
| Dependence on data | Can be small | Often decides the outcome |
| How a new version ships | New text or configuration | A new parameter file, further training, or a different architecture |
| How visible the insides are | Depends on how the text is written | Often hard: the contribution is spread across parameters |
After the table it helps to come back to the prime and the digit. Primality sits comfortably in the left column: the logic comes from a definition, new numbers are handled by the same rule, and an error can be localized. Reading handwriting sits in the right column: the source is examples and a fit, a new hand is not guaranteed, and the error shows up on a sample. You will not find it in one line. An industrial system usually occupies both columns at once. The model proposes a reading of the digit, and code beside it forbids a value outside the instrument's allowed range.
Four shelves, and none of them is a mind
The word "entity" jumps between meanings when people talk about models. Sometimes it means an object you can name, store, and tell apart from another object. Sometimes it means a system that performs a class of tasks. Sometimes it means an agent that acts in an environment. Sometimes it means a being with subjective experience. Moving from one shelf to the next does not happen by itself. A saved file does not become an agent because the file is large. An agent does not become a bearer of experience because it has a loop of actions.
In an engineering conversation a model has four shelves, and they are better kept apart.
On the first shelf is a description: architecture, training code, the chosen criterion. That is still a recipe, not an instance.
On the second shelf is saved state: the parameters after training. You can put them in storage, checksum them, roll them back.
On the third shelf is a running model. The parameters execute on hardware and handle requests. Latency and call cost show up here. So do hardware failure and a preprocessing mismatch with what was used in training.
On the fourth shelf is a system or an agent. The model is joined to memory and tools. Beside that sit a plan of steps and the channels through which the system sees the world and acts. Without that loop, the model answers a request and stops. An agent is a loop. It looks at a result, chooses an action, and receives a new result. The autonomy of that loop is set by the permissions and bans of the whole system. The character of the weight file has nothing to do with it. How that loop is assembled in a corporate setting is covered in the article on agents.
Functional independence can be described sparely. The system accepts input. It has internal state. It chooses among answers or actions. Tools are available to it, and it can change external state. There is feedback and an evaluation of the result. Such an object does something without a click-by-click script. Desire and subjective experience do not follow from that list. Mixing the shelves is expensive. A coherent answer does not mean a desire. Text without a source does not belong in a formal record.
Weights are not a handbook you can cite
Information is held in different ways, and the way it is held decides what you can do with it.
A document stores explicit claims. You can open a clause of a standard, quote it, and check it against a version number. A database stores structured records: a unit, a range, a date. Code sets operations and bans: if pressure is outside the range, the calculation does not continue. A model's parameters take part in transforming the input. A regularity in them may be spread across many numbers. One concept does not have to match one weight or one layer.
So weights cannot be read as an encyclopedia. Parameters affect one another. Pulling a specific fact back out is difficult and unreliable. The model may repeat a familiar pattern, mix details, and be confidently wrong. Interpretability research finds isolated understandable pieces in some networks and, at the same time, runs into the fact that a distributed representation is not a catalog card. The practical ban follows. Do not claim that a weight file holds an exact copy of the training documents. Even if the model retells a fragment, that is not a trace of "page 14, paragraph 2" until you have fetched the page from the source yourself.
A learned regularity and a checked fact diverge. The source holds a claim. The parameters may hold a statistical trace of that claim and traces of neighboring texts. At the output the model produces a wording. The wording becomes a checked fact after a comparison. At the moment of generation that comparison has not happened yet.
Industrial safety makes this visible on a single request. Suppose the system helps read technical standards. Further training on subject texts can improve vocabulary and the manner of the answer. It does not replace a clause of the current document version: standards change, and the parameter file is updated in a separate, expensive step. Source search built as RAG inserts a fragment and a link for the duration of the answer. Ordinary code checks units, ranges, and required conditions. An expert signs the conclusion when a mistake is expensive. Relying only on "knowledge in the weights" breaks exactly where you need a quotation, a version, and a traceable path.
When further training is appropriate, and when facts should stay outside the model, is covered in the note on fine-tuning. How to build document search so that the fragment and the quality check are part of the system is shown in the engineering treatment of RAG.
Sometimes the sheet on the wall is the honest tool
You can train a classifier of primes. On examples it will often hit the answer. Even numbers greater than two it learns quickly: the cue is crude and common in the sample. On an odd composite that was not in the training pages, it is allowed to be wrong, because it has no definition. It has only traces of the sample. The function that tests divisors up to the square root is wrong only if the text is broken. For a task with a known mathematical solution, the bench and the gauge come out expensive and less reliable. The sheet is shorter, cheaper, and easier to check.
The other extreme looks like a handwritten measurement. In a lab notebook a person writes "12.4", and the system has to read it. Rules about strokes and loops hold while the handwriting is familiar. A comma that looks like a dot, a smeared four, a digit that rides onto the ruling, inflate the sheet of exceptions. A recognizer trained on those images belongs here. It needs data from this handwriting and this form, a character-error metric, and a separate account of the dangerous mistake: reading the wrong pressure is worse than refusing and handing the page to a person. Where a lab for convolutional nets and line recognition starts is shown in the first lesson of the CNN and CRNN series.
The third case uses both tools. An assistant for technical standards does not reduce to a model alone, and it does not reduce to search alone. The model helps phrase the answer in the language of the subject. Search brings a fragment of the right version. Code checks that the units agree and the number sits inside the range. A person decides when safety depends on it. In this assembly the model remains a component of the architecture. It does not replace the architecture.
That is also why the limits belong in the piece. Without them, talk of the bench and the gauge turns into an advertisement. The sample may not represent the world you will see. Labels may be wrong. The setting may memorize the training pages and fall apart on new ones. The insides can be hard to read. Training and calls cost money and time. A new parameter version can quietly change behavior behind the same interface. An unexpected input knocks out an answer that was not in the test scenarios. Generative models invent plausible text. Critical areas need observation, repeated checks, and a person on the decision. If a task has an exact formal rule, write that rule on the sheet.
The developer sets the conditions under which an ability appears
Complex properties are not always written item by item. Sometimes an engineer sets a structure, constraints, and a process, and the behavior you wanted comes out as the result of that process. Machine learning shares that idea with other engineering fields, and the similarity ends there. Training remains a computational procedure with a chosen criterion. It is not biological evolution, and it is not a mind appearing on its own. The analogy helps you see the shift in the work. It does not prove anything extra.
It helps to keep three levels in mind, without offering them as the history of the field. On the first, the developer writes an algorithm. On the second, they build a process in which parameters are fitted from data. On the third, the model works with memory, tools, code, and feedback, and closes a task in several steps. The levels stack. The third does not cancel the first: a person still writes range checks in ordinary code.
The role changes in concrete actions. Instead of listing every handwriting, you choose representative pages. Instead of a hand heuristic for every curve, you design a penalty and a way to measure it. Instead of checking one branch of a condition, you look at which groups of examples the error grows on. Instead of shipping text alone, you version the data, the parameters, and the whole loop, including preprocessing. The main skill is to state the task so you can see which data could carry it at all. Then you choose a method and look at where the system fails, before you build it into a loop that can be stopped.
Further along the shop floor several directions are already visible, and none of them promises a system that sets its own goal. Hybrids of code, models, and knowledge bases become an ordinary assembly. Evaluation and further training are automated where the metric is already agreed with a person. Agents call tools inside the rights they were given. A loop can adjust to feedback when that feedback is labeled and bounded. A model version becomes a release artifact in the same way a code version is. Automating training and having a goal of one's own diverge. The first is already engineering practice. The second does not follow from it.
How a programmer's daily work changes when producing text gets cheaper is covered in the note on the programmer in the AI era. How a platform is assembled around a model, wider than a single chat, is shown in the piece on a corporate platform. How to measure such a loop so the number can be trusted is covered in the piece on evaluating enterprise AI.
FAQ
How does a trained model differ from a program?
In the narrow sense a program sets behavior in the text of rules. A trained model sets behavior by an architecture plus parameters fitted to data and an error criterion. In an industrial system the model almost always runs inside a program. The difference is in how the behavior is obtained. Neither of the two falls out of programming.
What is a trained model, briefly?
An architecture whose parameters have already been fitted to examples and a chosen error penalty, plus an agreement on the input format and the inference procedure. A weight file without the architecture code stores state. It does not become a running system.
Where does a neural network keep what it "knows"?
Explicit claims stay in documents and databases. Code stores bans and computations. Parameters may hold a distributed trace of regularities from the training data. That trace cannot be opened like a handbook page and cited as a source.
What are weights?
Numeric parameters that affect the transform from input to output. Training changes them. The same architecture with different weights may solve a task differently, or not solve it. Weights are saved to a file and loaded before a call.
Are a model and an algorithm the same thing?
The training algorithm remains a program that updates parameters. A trained model is what you get when that program has been run on data. The inference algorithm applies parameters already found to a new input. The words sit next to each other and mean different things.
How does a neural network train on data?
On an example, compute an answer with the current parameters, compare it to the label through a loss function, and shift the parameters so the penalty shrinks. For layered networks the backward pass gives the direction of the shift. Then look at examples that did not enter that shift.
When is an ordinary algorithm better than a model?
When the rule is known, complete, and checkable. Primality, units, a range, a required field, an exact formula. A model here is more expensive, harder to explain, and allowed to be wrong where the text of the rule would not be.
Is a model already an agent?
No. A model can emit an answer to one request and stop. An agent remains a system with a loop of steps, memory, and tools. It is allowed to change external state. A model becomes an agent only as part of such a system, and only inside the rights it was given.
Further reading
These pieces on the site continue individual shelves of this article.
- How language models are trained: parameters, document search, tools
- When further training is actually needed
- Industrial document search
- Neural network quality metrics
- The CNN and CRNN lab: where recognition starts
- Why corporate AI needs agents
- How to evaluate enterprise AI
Short external anchors for the terms: Google's introductory machine learning course (loss, gradient descent, generalization) and the PyTorch documentation on modules and parameters.
Conclusion
A program and a model are assembled into one system. A program can describe how to train. A model is what you get when that protocol has been run on data and the parameters have been saved. In a working loop they almost always lie together: the procedure sheet, the frame, the screws, the gauge, and a person who decides whether this setting may go onto the shop floor.
We used to write down, for the machine, how to solve the task. Now we can design a process that draws a way of solving from examples. The next engineering job is to make such systems checkable, controllable, and calm enough for a specific stretch of the work.
Comments